FSHybridPLS: Functional and Scalar Hybrid Partial Least Squares
An R package for penalized partial least squares when each observation carries both curves and scalars.
FSHybridPLS runs penalized partial least squares regression when a single observation carries both functional curves and scalar covariates — two renogram time series plus fifteen clinical measurements per patient, say. It compresses those tangled predictors into one supervised score that keeps the association with the response.
Classical functional regression asks how a curve predicts an outcome. Classical multivariate regression asks how a vector of scalars predicts an outcome. Modern biomedical data routinely give you both at once, and the two modalities live on incomparable scales: a curve carries infinitely many degrees of freedom and needs smoothing, while a scalar carries one and does not. FSHybridPLS is an implementation of Mun and Jang (2026), joint work with Jeong Hoon Jang (University of Texas Medical Branch), which handles the two modalities jointly rather than by concatenation.
The idea in one minute
The animation below walks through the whole method. It autoplays when it scrolls into view; you can pause it or drag the progress bar to any moment.
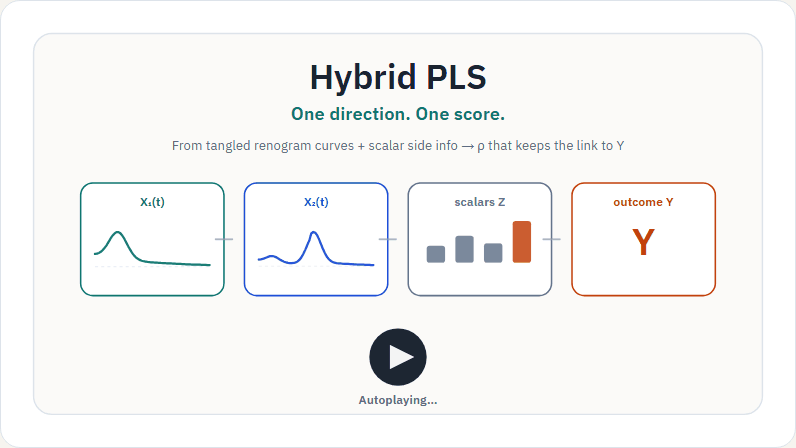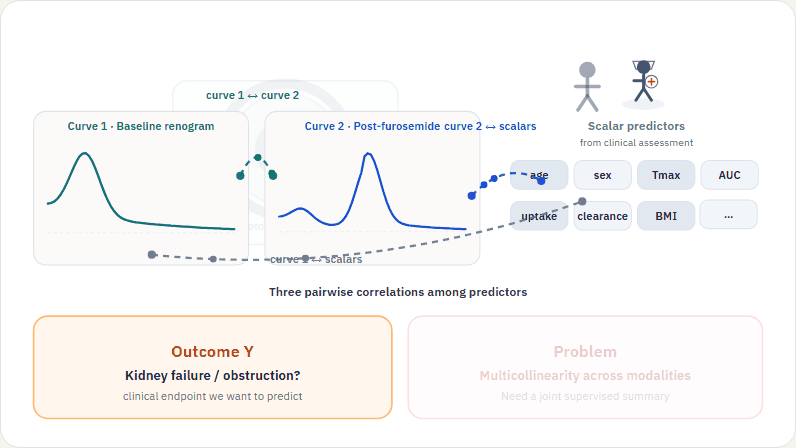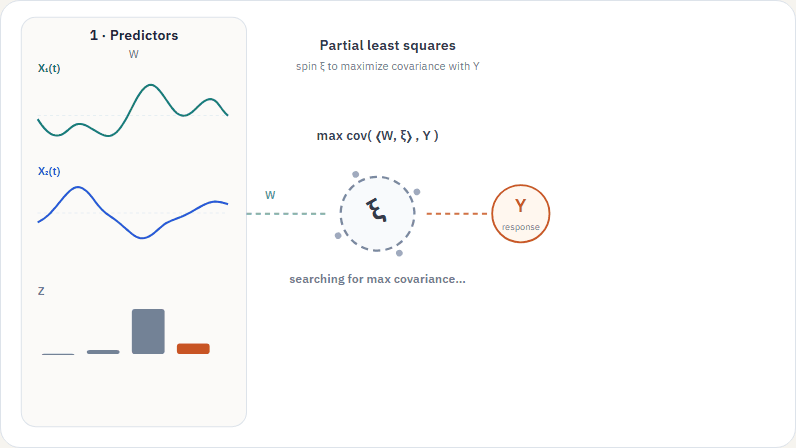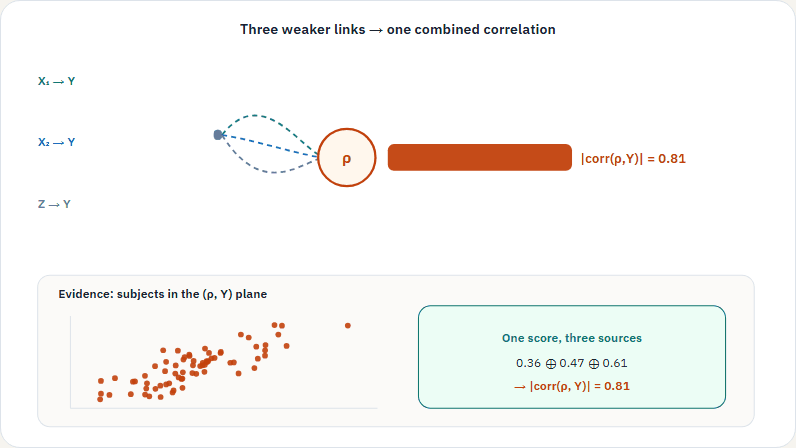
What the animation shows. A patient passes through the imaging scanner, which produces two renogram curves \(X_1(t), X_2(t)\); a nurse then records a vector of scalar measurements \(\mathbf{Z}\), and the clinical outcome \(Y\) is observed. Panel 1 shows that each modality is already correlated with \(Y\), and that the modalities are cross-correlated with each other, so the usable signal is scattered and partly duplicated. Panel 2 encloses all three blocks in a single hybrid predictor \(\mathbf{W} = (X_1, X_2, \mathbf{Z})\). Panel 3 is the algorithm proper: the weight object \(\boldsymbol\xi\) rotates until it maximizes the covariance between \(\langle \mathbf{W}, \boldsymbol\xi \rangle\) and \(Y\), and the resulting score \(\rho\) is assembled from two curve integrals plus one ordinary dot product. Panel 4 is the payoff: three individually weak associations are pooled into one score whose correlation with \(Y\) is stronger than any single block's. A looping GIF version is also available if the embedded player is blocked.
Method
One space for both modalities
The package treats a functional-and-scalar observation as a single point in a product Hilbert space, which is what makes “penalized PLS on mixed data” a well-posed geometric problem rather than a collection of heuristics.
An observation with \(K\) curves and \(p\) scalars is
\[\mathbf{W} = \bigl(X^{(1)}, \dots, X^{(K)}, \mathbf{Z}\bigr) \in \mathcal{H} = \underbrace{L^2([0,1]) \times \cdots \times L^2([0,1])}_{K \text{ times}} \times \mathbb{R}^p ,\]and \(\mathcal{H}\) is given the natural inner product, curve integrals plus the Euclidean dot product:
\(\langle \mathbf{W}, \boldsymbol\xi \rangle_{\mathcal{H}} = \sum_{k=1}^{K} \int_0^1 X^{(k)}(t)\, \xi^{(k)}(t)\, \mathrm{d}t \;+\; \mathbf{Z}^\top \mathbf{u}, \qquad \boldsymbol\xi = \bigl(\xi^{(1)}, \dots, \xi^{(K)}, \mathbf{u}\bigr).\)
Because addition, scalar multiplication and inner products are all defined on \(\mathcal{H}\), every step of PLS — projection, deflation, accumulation of coefficients — can be written once and applied to the whole hybrid object. In the implementation each curve is expanded in a B-spline basis, so an inner product is evaluated as \(\gamma_1^\top J_k \gamma_2\) with a precomputed Gram matrix \(J_k = \bigl(\int \phi_i \phi_j\bigr)_{ij}\): no numerical integration happens inside the fitting loop.
Roughness penalty
Curves are smoothed where they should be, by replacing the plain inner product with a penalized one that also charges for curvature. With \(R_k = \bigl(\int \phi_i'' \phi_j''\bigr)_{ij}\),
\[\langle \mathbf{W}, \boldsymbol\xi \rangle_{\lambda} = \langle \mathbf{W}, \boldsymbol\xi \rangle_{\mathcal{H}} + \sum_{k=1}^{K} \lambda_k \int_0^1 \bigl(D^2 X^{(k)}\bigr)(t)\, \bigl(D^2 \xi^{(k)}\bigr)(t)\, \mathrm{d}t .\]The smoothing parameters \(\lambda_1, \dots, \lambda_K\) act on the functional directions only; scalar covariates are never penalized, since there is no roughness to control.
The algorithm
Each iteration extracts one latent component, then deflates the data — the classical PLS loop, carried out in \(\mathcal{H}\).
-
Direction. Find the unit-norm weight object maximizing covariance with the current response residual:
\[\hat{\boldsymbol\xi} = \arg\max_{\|\boldsymbol\xi\|_{\lambda} = 1} \operatorname{cov}\bigl(\langle \mathbf{W}, \boldsymbol\xi\rangle_{\mathcal{H}},\, Y\bigr).\]This has a closed form. Each functional block solves the \(M \times M\) linear system \((J_k + \lambda_k R_k)\,\gamma_k = J_k \Theta_k^\top y\) in the basis coefficients, and the scalar block is simply \(\mathbf{u} = \mathbf{Z}^\top y\); the result is then rescaled to unit penalized norm.
-
Score. Project the predictors onto that direction, \(\rho_i = \langle \mathbf{W}_i, \hat{\boldsymbol\xi}\rangle_{\mathcal{H}}\).
-
Loadings. Regress the response and the predictors on the score.
-
Deflation. Subtract what the score explains from both the response and the hybrid predictors, and repeat.
-
Coefficient. Accumulate the components into one hybrid regression coefficient \(\hat{\boldsymbol\beta}_L \in \mathcal{H}\), so that prediction is again a single inner product, \(\hat{y} = \langle \mathbf{W}_{\text{new}}, \hat{\boldsymbol\beta}_L\rangle_{\mathcal{H}}\).
Notice what is not there: no \(p \times p\) matrix is ever inverted. The only linear systems are of size \(M \times M\), with \(M\) the number of basis functions per curve, so the cost grows linearly in the number of scalar covariates and the method stays usable when \(p\) exceeds the sample size.
Why concatenation is not enough
PLS is not scale invariant: whichever block carries more total variance dominates the first components. If you stack a densely sampled curve next to a handful of scalars, the curve wins by construction, not by relevance.
split_and_normalize_all() therefore standardizes in two stages. First within modality — curves are centered and scaled to unit integrated variance, scalars to unit variance, always with statistics computed on the training set only. Then between modalities: the scalar block is rescaled by \(\sqrt{\omega}\) with
so that the two modalities contribute comparable total variability and the extracted directions reflect predictive relevance instead of measurement density.
Installation
# Release version (once on CRAN)
install.packages("FSHybridPLS")

# Development version
remotes::install_github("Jong-Min-Moon/FShybridPLS")
The only hard dependencies are fda and stats.
Quick start
A complete, reproducible run: simulate a hybrid data set, preprocess it, fit three components, and score the held-out test set.
library(FSHybridPLS)
set.seed(1)

# One functional predictor (7 B-spline basis functions) plus three scalars
sim <- simulate_hybrid_data(n = 60, n_functional = 1, n_scalar = 3, n_basis = 7)

# Split, standardize within modality, balance across modalities, standardize y
prep <- split_and_normalize_all(sim$W, sim$y, train_ratio = 0.7)

fit <- fit_hybridPLS(
  prep$predictor_train,
  prep$response_train,
  n_iter = 3,
  lambda = 1e-3,                       # one smoothing parameter per functional predictor
  validation_data = list(
    W_test = prep$predictor_test,
    y_test = prep$response_test
  )
)

fit
#> Hybrid Penalized PLS model
#>   Components (n_iter): 3
#>   Functional predictors: 1
#>   Lambda: 0.001
#>   Validation RMSE by component:
#>     0.4832, 0.3402, 0.3759

preds <- predict(fit, prep$predictor_test)
sqrt(mean((prep$response_test - preds)^2))
#> [1] 0.3758842
Three things are worth knowing about the fitted object:
-
fithas classhybridPLS, withprint()andpredict()methods. -
predict(fit, newdata, n_components = k)truncates the model to the firstkcomponents, so you can inspect the whole complexity path without refitting. In the run above the second component is already the best one, which is exactly the choicecv_fit_hybridPLS()automates. -
fit$beta[[k]]is the cumulative coefficient afterkcomponents — itself a hybrid object, with a functional part and a scalar part you can plot and interpret.
For a narrated walkthrough in R:
vignette("FSHybridPLS", package = "FSHybridPLS")
Advanced usage
Tuning, then reading the fitted coefficient
The number of components and the smoothing parameters trade off against each other, so tune them together: cv_fit_hybridPLS() returns the whole RMSE-by-component curve for a given \(\lambda\), and wrapping it in a loop over a \(\lambda\) grid gives a small two-dimensional search.
library(FSHybridPLS)
set.seed(2)

sim  <- simulate_hybrid_data(n = 120, n_functional = 2, n_scalar = 5, n_basis = 9)
prep <- split_and_normalize_all(sim$W, sim$y, train_ratio = 0.7)

lambda_grid <- 10^seq(-6, -1, length.out = 6)

cv_path <- do.call(rbind, lapply(lambda_grid, function(lam) {
  cv <- cv_fit_hybridPLS(
    prep$predictor_train,
    prep$response_train,
    n_iter = 6,
    lambda = rep(lam, prep$predictor_train$n_functional),
    n_fold = 5,
    seed = 1
  )
  data.frame(lambda = lam, n_comp = cv$best_n_iter, cv_rmse = min(cv$rmse_by_component))
}))

cv_path <- cv_path[order(cv_path$cv_rmse), ]
best <- cv_path[1, ]

fit <- fit_hybridPLS(
  prep$predictor_train,
  prep$response_train,
  n_iter = best$n_comp,
  lambda = rep(best$lambda, prep$predictor_train$n_functional)
)

sqrt(mean((prep$response_test - predict(fit, prep$predictor_test))^2))
The selected model is a single hybrid coefficient, so it can be read directly: plot the functional part as a curve \(\hat\beta^{(k)}(t)\), which shows when along the domain the curve matters, and read the scalar part as ordinary regression weights.
beta   <- fit$beta[[fit$n_iter]]
t_grid <- prep$predictor_train$eval_point

# Functional part: one coefficient curve per functional predictor
beta_curves <- sapply(beta$functional_list, function(fd_obj) fda::eval.fd(t_grid, fd_obj))

matplot(
  t_grid, beta_curves, type = "l", lty = 1, lwd = 2,
  xlab = "t", ylab = expression(hat(beta)(t)),
  main = "Estimated functional coefficients"
)
abline(h = 0, col = "grey70", lty = 3)
legend("topright", legend = paste("curve", seq_len(ncol(beta_curves))),
       lty = 1, lwd = 2, col = seq_len(ncol(beta_curves)), bty = "n")

# Scalar part: weights on the standardized scalar covariates
scalar_weights <- setNames(drop(beta$Z), colnames(sim$W$Z))
barplot(sort(scalar_weights), horiz = TRUE, las = 1,
        xlab = "coefficient", main = "Scalar covariate weights")

Z5.Coefficients live on the standardized scale produced by
split_and_normalize_all(). That is exactly what you want for comparing covariates with each other; convert back with the stored normalization statistics inprep$detailsbefore interpreting a coefficient in original units.
Many scalar covariates, more than observations
Because the algorithm never inverts a \(p \times p\) matrix, a wide scalar block is not a problem — the scalar weight step is one matrix–vector product. Below, 200 scalar covariates accompany a curve for only 90 subjects, and the magnitude of the scalar coefficients is used to screen for the covariates that actually drive the score.
library(FSHybridPLS)

# 200 scalar covariates for 90 subjects, plus one curve each
sim <- simulate_hybrid_data(n = 90, n_functional = 1, n_scalar = 200, n_basis = 7, seed = 3)

set.seed(11)
prep <- split_and_normalize_all(sim$W, sim$y, train_ratio = 0.7)

cv <- cv_fit_hybridPLS(
  prep$predictor_train, prep$response_train,
  n_iter = 8, lambda = 1e-3, n_fold = 5, seed = 1
)
cv$rmse_by_component      # validation RMSE as complexity grows
cv$best_n_iter

fit <- fit_hybridPLS(
  prep$predictor_train, prep$response_train,
  n_iter = cv$best_n_iter, lambda = 1e-3
)

# Rank scalar covariates by their contribution to the score (training data only)
weights <- setNames(abs(drop(fit$beta[[fit$n_iter]]$Z)), colnames(sim$W$Z))
head(sort(weights, decreasing = TRUE), 10)

# Refit on the 20 strongest covariates, keeping the train/test split fixed
keep <- names(sort(weights, decreasing = TRUE))[1:20]

W_small <- predictor_hybrid(
  Z               = sim$W$Z[, keep, drop = FALSE],
  functional_list = sim$W$functional_list,
  eval_point      = sim$W$eval_point
)

set.seed(11)   # same seed and sample size => same split indices as above
prep_small <- split_and_normalize_all(W_small, sim$y, train_ratio = 0.7)
stopifnot(identical(prep$details$split_indices, prep_small$details$split_indices))

fit_small <- fit_hybridPLS(
  prep_small$predictor_train, prep_small$response_train,
  n_iter = cv$best_n_iter, lambda = 1e-3
)

sqrt(mean((prep_small$response_test - predict(fit_small, prep_small$predictor_test))^2))
This is coefficient-magnitude screening, not a sparsity penalty: PLS shrinks coefficients but never sets them to zero, so the cut-off at 20 is a modeling choice. In this particular simulation every one of the 200 true scalar coefficients is nonzero, so the screened refit actually predicts slightly worse than the full model — which is the useful lesson. Screening buys interpretability, and repays it in accuracy only when the truth really is sparse. Note also that the ranking above comes from the training fit alone, and the split is held fixed so both models are scored on the same held-out subjects; for a reportable error estimate, repeat the screening inside every cross-validation fold rather than once outside.
What is in the package
Public functions use underscores; the dotted names from the paper’s replication scripts (fit.hybridPLS, inprod.predictor_hybrid, split_and_normalize.all) remain as thin aliases with identical numerics.
| Function | Role |
|---|---|
predictor_hybrid() | Build a hybrid predictor from a scalar matrix and a list of fd objects |
simulate_hybrid_data() | Simulate hybrid predictors, a response, and the true coefficient |
split_all() | Train/test split without normalization |
split_and_normalize_all() | Split, within-modality and between-modality normalization, response standardization |
fit_hybridPLS() | Fit hybrid penalized PLS; returns a hybridPLS object |
predict(), print() | S3 methods for hybridPLS |
cv_fit_hybridPLS() | Choose the number of components by K-fold cross-validation |
create_idx_kfold() | K-fold train/validation indices |
inprod_predictor_hybrid() | Hybrid inner product |
inprod_pen_predictor_hybrid() | Roughness-penalized hybrid inner product |
load_and_preprocess_kidney_data() | Turn a renogram-style data frame into (W, y) |
Lower-level machinery — hybrid arithmetic, deflation helpers, the direction solver get_xi_hat_linear_pen(), the individual normalizers — is documented and available, but the high-level functions above cover typical analyses.
Application: renogram curves
The method was developed for a nuclear-medicine problem in which each patient contributes a baseline renogram and a post-furosemide renogram, both sampled on a time grid, together with age and fourteen physiological summaries. load_and_preprocess_kidney_data() encodes that pipeline: both curves are peak-normalized by the baseline maximum (preserving the relative magnitude of the post-furosemide response), smoothed into B-splines on \(t \in [0,1]\), and combined with the scalar covariates into one predictor_hybrid; the response is the average of three expert ratings, min–max scaled to \([0,1]\).
data <- load_and_preprocess_kidney_data(my_renogram_df, n_basis = 20)
prep <- split_and_normalize_all(data$W, data$y, train_ratio = 0.7)
The helper is application-specific and needs your own data frame; the core algorithm does not depend on it. Scripts reproducing the paper’s geometric validation, coefficient-estimation study, two prediction scenarios, and the kidney analysis (against OLS, principal component regression, and penalized functional regression) live under numerical_studies/ in the GitHub repository and are not shipped inside the package tarball.
Citation
citation("FSHybridPLS")
Mun, J. and Jang, J. H. (2026). Hybrid Partial Least Squares Regression with Multiple Functional and Scalar Predictors. arXiv:2601.16364. https://doi.org/10.48550/arXiv.2601.16364
Source code and issue tracker: https://github.com/Jong-Min-Moon/FShybridPLS. Released under the MIT license.